News
Subscribe to the Australian BioCommons monthly newsletter or read previous editions
New Insights into childhood cancer: sharing data to transform precision medicine
In November, Children’s Cancer Institute will launch Insights, a new platform that makes data from the ZERO Childhood Cancer Program easier to discover, explore and request. Insights was developed through the GUARDIANS Program at Australian BioCommons.
In November, Children’s Cancer Institute will launch Insights, a new platform that makes data from the ZERO Childhood Cancer Program easier to discover, explore and request.
Designed by and for researchers, Insights changes the experience of finding and accessing data. Until now, the only way to know whether data could answer a research question was to apply for it. How many children carry the variant of interest? Was RNA-sequencing done? Is the data published, or still embargoed? Finding out has meant emails, applications and long waits, often weeks or months, sometimes only to learn the data won’t do the job. That’s time lost to research that could help children with cancer, and valuable data left underused.
With Insights, researchers explore first and request second, so they can spend less time chasing data and more time using it.
Ask the question, see the answer
ZERO is a world-leading precision medicine program bringing together clinicians and researchers across Australia and internationally. The ZERO dataset is a rich and rare resource for childhood cancer research: over 3,500 participants, more than 15,000 samples and over 200 patient-derived xenograft (PDX) models. Insights puts ZERO’s clinical and molecular data in one place for researchers, bioinformaticians, clinicians and molecular tumour board members.
Everyone starts in Insights the same way: searching by diagnosis, gene, variant or study, then stacking filters across cancer type, participant, sample and molecular data. Counts update live. Within minutes, a researcher can see whether a viable cohort exists, and a clinician can check how often a variant or subtype has appeared across ZERO. Bioinformaticians can create virtual cohorts in preparation for downstream analysis.
When the data looks right, one click turns the query into a data access request for FASTQ, BAM/CRAM and VCF files, expression matrices or methylation array data. The whole process is transparent: researchers can see where their request stands at every step, from review through to delivery.
Shared safely, used widely
Childhood cancers are rare, and many subtypes are rarer still. No single hospital, study or country sees enough cases to answer the questions that matter most. Progress depends on sharing data carefully and at scale, so that what we learn from one child can help the next.
The data in ZERO exists because thousands of children and their families chose to contribute to research. Insights is designed to make that contribution go as far as it can. It is open enough for researchers to find what they need, and governed closely enough to protect the trust those families have placed in the ZERO program.
Anyone can log in and explore summary-level data, including cohort counts and distributions, and researchers can sign in with their institutional credentials. Detailed and participant-level data stays behind established access processes: approval decisions are guided by participant consent, data agreements and the Institute’s legal and policy requirements. Insights holds no directly identifiable information.
Built to be reused
Insights was developed through GUARDIANS, the Australian BioCommons-coordinated national infrastructure program for secure discovery, access and analysis of human genomics data. GUARDIANS is supported by Bioplatforms Australia, enabled by NCRIS.
Insights uses an HL7 FHIR-based data model and recognised ontologies to harmonise clinical, molecular and biospecimen data. It follows FAIR principles and aligns with relevant GA4GH approaches, with carefully managed extensions where paediatric cancer data needs them. The code is planned for open-source release so others can adapt it for their own datasets.
Insights will keep growing. Over the next 18 months, funded development will expand what can be discovered, adding more biospecimen types, more molecular data (including germline findings), drug screening results and AI capabilities. If your organisation has data that could be shared through Insights, please contact the team at insights@ccia.org.au.
See Insights in action
Join Children’s Cancer Institute and Australian BioCommons for a webinar on Wednesday 25 November, 1–2 pm AEDT. We’ll show how to access Insights, discover and explore ZERO data, build and save queries, and submit a data access request from start to finish.
Building a national rare disease research platform
A new Medical Research Future Fund grant for National Critical Research Infrastructure, announced in July 2026, will expand CaRDinal, a secure, cloud-based platform purpose-built for collaborative rare disease genomic analysis supported by the GUARDIANS Program.
A new Medical Research Future Fund (MRFF) grant for National Critical Research Infrastructure, announced in July 2026, will expand CaRDinal into a national research infrastructure for rare disease studies across Australia. Supported by the GUARDIANS Program, CaRDinal is a secure, cloud-based platform purpose-built for collaborative rare disease genomic analysis.
CaRDinal was launched in 2022 by the Centre for Population Genomics, and is designed to be used directly by clinical researchers as well as bioinformaticians. Without needing to write code or run their own analyses, they can explore a family's genetic variants and pinpoint the change most likely to explain their condition. With the benefit of data from many studies processed the same way in one place, it becomes easier to find the same gene implicated in unrelated families, which is often the key to identifying a new disease gene.
Since 2024, CaRDinal's growth has been supported by the GUARDIANS Program, which has helped new research cohorts join the platform.
‘Every cohort that joins CaRDinal makes the platform more useful for everyone on it, because each new family increases the chance of finding a match for someone else,’ says Dr Cas Simons, Rare Disease Program Lead at the Centre for Population Genomics.
‘The new MRFF funding means we can open CaRDinal up to rare disease researchers right across the country and help bring answers to more families sooner.’
Why is a platform like CaRDinal needed?
More than two million Australians live with a rare disease, yet over half of those who undergo genomic testing remain undiagnosed. Often, this is a data and tooling problem, as the causative genes have not yet been discovered, there is no routine way to revisit static data when new genes are identified, and clinical researchers frequently lack the bioinformatics tools to explore complex genomic datasets themselves.
CaRDinal enables research groups studying rare diseases to bring their patients' genomic data onto the platform, where it is processed in a consistent way and made ready for analysis. As of September 2026, CaRDinal holds genomic data from more than 11,600 people in over 5,700 families living with a rare disease, drawn from over 40 research cohorts across Australia, making it the largest accessible collection of rare disease genomic data in the country.
Over 400 researchers have used the platform, contributing to over 1,000 genetic diagnoses and many new discoveries.
How can unresolved cases be reanalysed?
Bringing data together on a shared platform also makes it possible to tackle a persistent barrier to diagnosis - revisiting unsolved cases as knowledge grows. Every year, hundreds of new disease genes and disease-causing variants are reported, so a family whose genomic test found no answer a few years ago may have one today.
To address this, the Centre for Population Genomics developed Talos, an open-source tool that automatically compares genomic data against the latest knowledge of disease genes and variants. Talos is now integrated with CaRDinal and reanalyses families on the platform every month, flagging new candidate diagnoses for research teams to review.
Visit the CaRdinal website
Start using Talos
The Centre for Population Genomics is a joint national initiative of Garvan Institute of Medical Research and Murdoch Children’s Research Institute.
The GUARDIANS program is accelerating human omics research in Australia through the development of world-class digital infrastructure. The program is led by Australian BioCommons with contributions from partner organisations including the Australian Access Federation, Children’s Cancer Institute Australia, Garvan Institute of Medical Research, National Computational Infrastructure, QIMR Berghofer Medical Research Institute, The University of Melbourne, and The University of Sydney. GUARDIANS forms part of Australian BioCommons’ Human Genome Informatics Initiative and receives National Collaborative Research Infrastructure Strategy support through Bioplatforms Australia.
Connect with BioCommons staff at eResearch Australasia 2026
Many of the Australian BioCommons team and partners working on our projects will be presenting at the next eResearch conference from 26 - 30 October 2026. Here's a snapshot of ways to hear about our ongoing developments.
The eResearch Australasia Conference offers delegates interested in information-centric research capabilities the chance to engage, connect, and share their ideas. Sessions will cover how information and communication technologies help researchers to collaborate, collect, manage, share, process, analyse, store, find, understand, and re-use information.
A diverse range of BioCommons activities will be on show at the conference, presented by BioCommons staff and our collaborators. Please join us at the sessions below!
Presentations & Oral Sessions
Tuesday 27 October, 3:50 pm - Oral Presentation: Understanding AI opportunities and challenges of the molecular life science community: findings from national consultation (Dr Benjamin Goudey)
Thursday 29 October, 11:20 am - Presentation: GUARDIANS: an Australian digital research ecosystem built for the demanding requirements of human omics research (Prof Bernie Pope)
Thursday 29 October, 12:00 pm - Presentation: Infrastructure as an onramp: BioShell as a portable bioinformatics environment with open tools (Dr Georgie Samaha & Dr Mitchell O'Brien)
Thursday 29 October, 1:40 pm - Presentation: From Models to Services: Software for Accessible AI Structural Biology (Dr Thomas Litfin & Anne Phan)
Lightning Talks
Thursday 29 October, 12:00 pm - Lightning Talk: Product Ownership: Our Secret Weapon for Taming Research Infrastructure Chaos (Lisa Phippard & Dr Nigel Ward)
Posters
Poster: Mapping Artificial Intelligence in Galaxy Australia: Integration, Data Flows and Governance (Dr Anna Syme)
We look forward to catching up with many of you in person at the conference!
Turning raw data into published genomes faster with the Australian Tree of Life Genome Engine
The Australian Tree of Life (AToL) Genome Engine is enabling rapid, automated genome assembly, annotation and publication, turning raw sequence data in reference genomes for Australian birds, fish, threatened species and more.
The Black-Eared Miner genome has become openly available as part of the effort to uplift the generation, publication and re-use of reference genomes for Australian species. Like a lot of sequence data, the bird’s genome remained unassembled until now because the process of transforming raw sequence data into genome assemblies for downstream analyses is time-intensive and computationally expensive. The Australian Tree of Life (AToL) Genome Engine changes the equation by enabling rapid, automated genome assembly, annotation and publication.
Sequenced as part of the Threatened Species Initiative in 2023, the Black-Eared Miner genome was recently ingested into the AToL Genome Engine for assembly and rapidly deposited in the European Nucleotide Archive (ENA) to achieve maximum reach and utility of the data.
Under development from the AToL Bioinformatics team at BioCommons, the Genome Engine accelerates the assembly and annotation of genomic data generated by Bioplatforms Australia’s Framework Initiatives. The first of the Australian Venom Innovation and Discovery Initiative’s (AVID) genome assemblies, describing the native bag-shelter moth or processionary caterpillar, Ochrogaster lunifer, has also been submitted to ENA. AVID data is currently only available to researchers in the AVID Initiative, but will become publicly available after an embargo period. The code base used to generate each assembly is also published in GitHub.
How does the Genome Engine work?
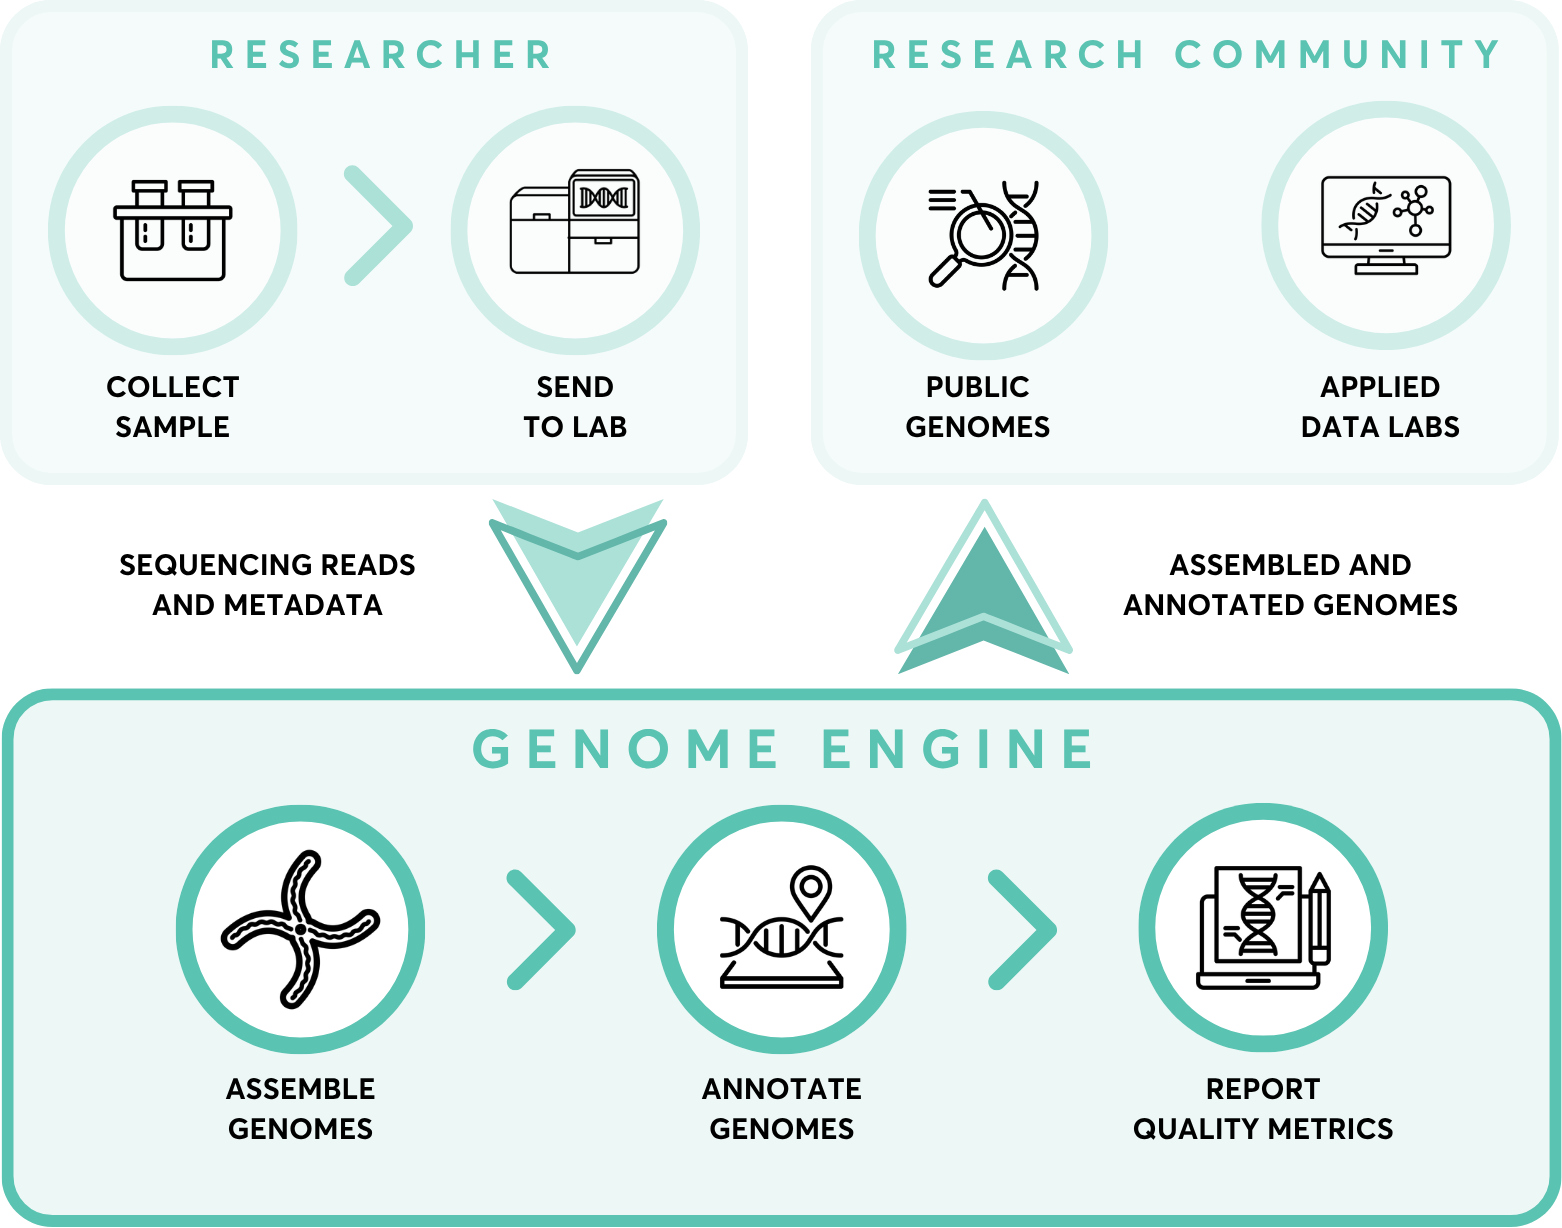
The Genome Engine is a semi-automated workflow for assembling and annotating genome sequences from raw sequence data, brokering data to International Nucleotide Sequence Database Collaboration (INSDC) repositories.
This involves:
Ingesting raw sequence data from the Bioplatforms Australia Data Portal
Processing sampling and sequencing metadata
Assembling genome sequences from sequence read data
Annotating assembled genomes
Brokering sample metadata, sequence reads, and genome assemblies to the ENA
Providing details and metrics about sampling, sequencing and assembly
How the AToL Genome Engine works
Who can use the Genome Engine?
So far, the Genome Engine has been refined by exposing it to the needs of the Bioplatforms Framework Initiatives. These large research consortia have provided diverse genomes representing Australian fish and birds, threatened species, and venomous animals. While it is configured to ingest data available from the Bioplatforms Australia Data Portal, the Genome Engine will eventually be made available to all Australian researchers.
If you have interesting sequencing data of a species significant to Australia, get in touch to see if you can benefit from this expanding scope. Otherwise stay tuned for when the AToL Genome Engine launches as a service open to all Australian researchers.
View the Black-Eared Miner genome draft assembly
Find out more about the AToL Genome Engine
Contact the team if you have a genome sequence of an Australian species needing assembly: atol-bioinformatics@unimelb.edu.au
AToL Bioinformatics is co-funded by Bioplatforms Australia and Minderoo Foundation, with project partners at the University of Melbourne, QCIF, the European Nucleotide Archive, and the Darwin Tree of Life.
The AToL Genome Engine was inspired by the Wellcome Sanger Institute’s Genome Engine, and uses some of their pipelines under the hood.
Strengthening global biodata sustainability: Australia joins international advisory leadership
BioCommons Director, Dr Jeff Christiansen, has been appointed to the Scientific Advisory Committee of the Global Biodata Coalition, working alongside global data experts to guide strategic approaches for funding and sustainability of digital infrastructure.
Australian BioCommons Director, Dr Jeff Christiansen, has been appointed to the Scientific Advisory Committee (SAC) of the Global Biodata Coalition (GBC). In this international role, he will work alongside global data experts to guide strategic approaches for funding and sustaining the critical digital infrastructure that underpins modern life science research.
Securing the digital foundation of life sciences
Biological, biomedical, agricultural and environmental research relies heavily on open-access global data repositories - from sequence archives to protein structure knowledgebases.
In addition to underpinning human scientific endeavour for many decades, these highly curated, high quality resources are now also enabling ground breaking AI-tools like AlphaFold to be developed. However, sustaining these data resources long-term remains a systemic challenge worldwide, as many repositories depend on short-term competitive grants or localised funding streams.
The GBC convenes major research funding agencies from around the world to address this fragility - including Wellcome (UK), National Institutes of Health (USA), National Science Foundation (USA), State Secretariat for Education Research & Innovation SERI (Switzerland), United Kingdom Research & Innovation, Research Council of Norway, Chan Zuckerberg Initiative (USA), Genome Canada, European Molecular Biology Laboratory and the African Academy of Sciences.
By building shared frameworks and identifying Global Core Biodata Resources (GCBRs), the GBC works to ensure that primary scientific data assets remain freely available, stable, and protected against shifts in national budgets.
The GBC recently entered a major expansion phase supported by Horizon Europe funding and hosted by the European Molecular Biology Laboratory - European Bioinformatics Institute (EMBL-EBI).
Bringing an Australian perspective to global governance
The GBC Scientific Advisory Committee provides independent expert advice directly to the GBC Board of Funders and Secretariat on scientific priorities, computational trends, and international infrastructure alignment. Members are invited as independent global experts to help guide sustainability strategies across life science domains.
Australian research relies heavily on core international repositories, with our researchers submitting millions of requests per year to databases hosted at EMBL-EBI alone. This demand will only increase as digital infrastructure, data stewardship and AI become more central to research. The Australian Government’s strategic financial contribution through the National Collaborative Research Infrastructure Strategy (NCRIS) towards Australia’s associate membership in EMBL helps sustain the core infrastructure supporting these repositories, demonstrating the principle of global co-investment advocated by the GBC. Further NCRIS investment via Bioplatforms Australia and others into activities such as Australian BioCommons, and EMBL Australia, also ensures that domestic researchers can better access, utilise and submit data to these worldwide repositories.
"Sustaining global data resources is vital for the entire biological scientific enterprise. Having participated in GBC’s Global Core Biodata Resource selection panels over recent years, I am honoured to now join the Scientific Advisory Committee. I look forward to bringing both an Australian and international digital infrastructure perspective to help shape stable, long-term funding models for these foundational resources." - Jeff Christiansen. Director, Australian BioCommons
Heading to Cambridge for GBC26
In October 2026, Jeff will travel to Cambridge, UK, to participate in in-person SAC meetings and a joint summit with the GBC Board of Funders.
He will also represent Australian BioCommons at the inaugural Global Biodata Conference (GBC26) on 7-8 October. This conference brings together international funders, database managers, and computational biology leaders to explore pooled funding models, public-private partnerships, and strategies to broaden infrastructure participation across low- and middle-income countries.
To learn more about the coalition’s mission and Global Core Biodata Resources, visit the Global Biodata Coalition website.
Read more about the Global Biodata Coalition’s Scientific Advisory Committee
Explore how Australian BioCommons engages internationally via our Collaborations page.
Removing barriers: academia and industry collaborate to open commercial access to protein design software
A collaborative effort from academia and industry has made a popular protein design software package free for commercial use, removing a significant barrier for biotechnology companies wanting to use the pipeline.
A collaborative effort from academia and industry has made a popular protein design software package free for commercial use. All previously restricted components have now been replaced, removing a significant barrier for biotechnology companies wanting to use the pipeline.
Making AI-powered protein design more accessible
Tools such as AlphaFold2 and RFDiffusion have dramatically expanded researchers’ ability to predict and design protein structures, opening new possibilities for engineering proteins with useful biological functions. However, taking full advantage of these new tools can still present significant technical barriers.
ProteinDJ was developed to make these powerful methods easier to use.
Contributors for the ProteinDJ V3.0 release: WEHI. Australian BioCommons, UNSW Sydney, and Audax
Originally developed and published by Dylan Silke, Dr Josh Hardy and Prof Isabelle Lucet, from the Papenfuss and Lucet laboratories at WEHI, ProteinDJ streamlines the protein binder design process into a single, modular workflow that is easy to install, efficient to run and flexible enough to incorporate new methods as the field evolves. It guides the user through four key stages: designing a binder’s shape (fold), generating an amino acid sequence for it, predicting a 3D structure and analysing the results.
While ProteinDJ itself is open source, some of the software components it relied upon carried licences that restricted how the workflow could be used and distributed. These restrictions presented practical barriers to broader adoption, particularly within biotechnology companies. Dr Josh Hardy (WEHI), Dr David Ladd (Audax), and Dr Thomas Litfin (Australian BioCommons/UNSW) have now worked together to remove these barriers alongside a range of other improvements as part of the release of ProteinDJ version 3.0.
From webinar to collaboration and national capability
As part of the Leveraging deep learning to design custom protein-binding proteins webinar series developed by the Australian Structural Biology Computing community, Australian BioCommons hosted a ProteinDJ webinar in late 2025. The popular presentation was seen by researchers at the Australian biotechnology company, Audax, who are developing targeted immunotherapies for oncology and autoimmune diseases. Identifying the potential of the ProteinDJ pipeline, they began work to replace the licensed dependencies. Simultaneously, Australian BioCommons had been working with the ProteinDJ developer, Dr Josh Hardy, to address the license restrictions. In mid-2026, the groups joined forces and began working collaboratively to merge and validate the new components alongside several performance and usability improvements.
This work paves the way for ProteinDJ to be incorporated into the Australian BioCommons Structural Biology Platform, which is currently being developed with the research community, and will soon become available for Australian researchers to run AI-based structural biology workflows.
Check out ProteinDJ on GitHub
Read the publication - ProteinDJ: A high-performance and modular protein design pipeline
View the ProteinDJ webinar recording
Connecting complex health datasets for research and translational impact
The open-source data platform, Gen3, is able to support robust data ecosystems that are tailor-made for their users. Australian BioCommons is supporting multiple deployments through the GUARDIANS Program, helping national consortia management and share their human omics data holdings between research collaborators.
A secure, interconnected approach to managing massive health datasets is enabling Australian researchers to accelerate the path from biological discovery to clinical treatment across multiple disease areas. By establishing shared digital infrastructure for complex genomic, multi-omic, and clinical data, national research teams can now pool resources, protect sensitive information, and collaborate at an unprecedented scale.
The open-source data platform, Gen3, is able to support robust data ecosystems that are tailor-made for their users. Australian BioCommons is supporting multiple deployments through the GUARDIANS Program, helping national consortia manage and share their human omics data holdings between research collaborators.

Originally developed at the University of Chicago to power National Institutes of Health (NIH) initiatives, Gen3 provides a secure and scalable framework to receive, manage, and describe large-scale datasets while ensuring secure, governed access for authorised users. BioCommons helped establish the international Gen3 Community Forum, and regularly interacts with the rapidly growing community of people wrangling large and complex research datasets in the cloud.
Prof Bernard Pope, GUARDIANS Program Lead and A/Director (Human Genome Informatics) at Australian BioCommons, highlights the value of this approach:
‘Data commons are a key factor in impactful and collaborative genomic research. The ability to securely connect, govern, and analyse large datasets is increasingly important for translating research into meaningful clinical and health outcomes.’
‘Through the GUARDIANS Program, we have leveraged the capabilities of the Gen3 platform, which has already extensively been used by researchers on the global scale, to ensure Australian researchers have the tools to effectively work with the available genomic data.’
How is Gen3 being used in Australian health research?
BioCommons is implementing Gen3 platforms for multiple landmark national projects, demonstrating its versatility across diverse data types and research fields:
Australian Cardiovascular disease Data Commons (ACDC): Led by the Baker Heart and Diabetes Institute, the ACDC securely pools multi-omics data, longitudinal outcomes, and imaging from approximately 400,000 individuals across 18 Australian cohorts to discover new risk markers for heart attacks
Biological Psychiatry Data Commons (BPsyc-DC): Developed in partnership with the Consortium for Preclinical Psychiatric Research (CPPR), the BPsyc-DC will provide a national digital infrastructure to harmonise multi-omics data across cellular, animal, and human models of psychiatric disorders
Px4 Health: Led by the University of Melbourne, Px4 Health utilises cutting edge multi-omics technology and deep phenotyping to deliver an Australian first for personalised medicine. By providing a secure, end-to-end data solution, Px4 Health is underpinning major clinical initiatives in rare and chronic disease, as well as establishing a baseline of health data on a cross section of the community.
Supported by recent additional NCRIS funding, GUARDIANS will implement additional data commons to expand participation for new priority health areas.
Register for the upcoming webinar ‘Launching the Australian Cardiovascular disease Data Commons’
Read more about the Biological Psychiatry Data Commons
Building the Biological Psychiatry Data Commons
The development of a new national resource is underway that will unite pre-clinical models, data and researchers to better understand mental disorders at the molecular level.
The development of a new national resource is underway that will unite pre-clinical models, data and researchers to better understand mental disorders at the molecular level. It will support the discovery, management and analysis of harmonised multi-omics data across diverse psychiatric model systems, allowing researchers to move faster from discovery to clinical impact.
The Biological Psychiatry Data Commons (BPsyc-DC) is being built through a partnership between Australian BioCommons, Phenomics Australia, the Australian Research Data Commons (ARDC), Bioplatforms Australia and the Consortium for Preclinical Psychiatric Research (CPPR). It builds on the Australian Psychiatric Research Knowledge Bank initiative from the CPPR in conjunction with Bioplatforms Australia, which brings together CPPR-associated biosamples and datasets generated in partnership with national infrastructure organisations
The CPPR is a national collaboration led by Monash University researchers Prof Rachel Hill and Prof Suresh Sundram, and provides coordination and leadership for a nation-first effort to standardise and integrate large-scale molecular data generated from cellular, animal and human models of psychiatric disorders.
‘The new Biological Psychiatry Data Commons will provide shared digital infrastructure, governance frameworks and interoperability,’ said Prof Rachel Hill.
‘It will support the progression from curated datasets toward an integrated, reusable national resource, and will help us accelerate the translation of biological discoveries into real-world clinical outcomes.’
How will a data commons impact preclinical research into mental disorders?
Mental disorders are among the leading contributors to disease burden in Australia and globally, yet progress toward biomarkers and disease-modifying treatments has been limited. Diagnoses remain largely symptom-based, and existing treatments are often only partially effective and are associated with significant side effects. This represents a major unmet medical need for individuals, families and communities affected by mental illness.
A key barrier to progress in biological psychiatry is the fragmentation of research data. Insights into disease mechanisms are generated across cellular, animal and human studies, but these data are typically siloed, modest in scale, and challenging to integrate. The absence of shared infrastructure to harmonise, manage and analyse data across model systems limits statistical power, slows discovery, and constrains translation into clinical impact.
At its core, the BPsyc-DC is a cloud-based data platform with appropriate ethical oversight and governance, enabling the research community to manage, analyse and share sensitive data responsibly while maximising reuse and impact.
The BPsyc-DC is designed to:
Support harmonisation of multi-omics data across cellular, animal and human psychiatric models
Enable secure, governed access to data under CPPR-led ethical and data governance frameworks
Improved discoverability and reuse of psychiatric research data through FAIR principles and national catalogues
Facilitate scalable, cross-cohort and cross-model analyses that increase statistical power and biological insight
Interoperate with national and international research data infrastructure to support collaboration and sustainability.
As a foundational capability, the BPsyc-DC is built to expand over time. Future directions include the incorporation of additional data types (such as epigenomics, metabolomics, lipidomics, and immune or inflammatory phenotyping), scaling to support a broader range of mental disorder models, and integrating secure analytics environments and AI-enabled tools to enhance hypothesis generation.
Read more about the Biological Psychiatry Data Commons
Simplifying data movement for faster analysis: the new link between the Bioplatforms Data Portal and Galaxy Australia
A new one-click data transfer feature now connects the Bioplatforms Data Portal directly to Galaxy Australia. Powered by BioCommons Access, this integration lets researchers instantly send large datasets straight to the analysis platform without having to switch.
Moving data is a key part of the research workflow, and can become a bottleneck if there’s significant separation between steps. Researchers are increasingly using multiple services and have to take on the role of the ‘network switch,’ moving their data back and forth to complete isolated functions.
A new data movement feature streamlines the connection between data and analysis, with a fast one-click transfer of data from Bioplatforms Data Portal for immediate analysis using the fully-subsidised Galaxy Australia service. By selecting your data and clicking 'Send to Galaxy', the previously manual process happens automatically and invisibly in the background - appearing in your Galaxy history ready for analysis.
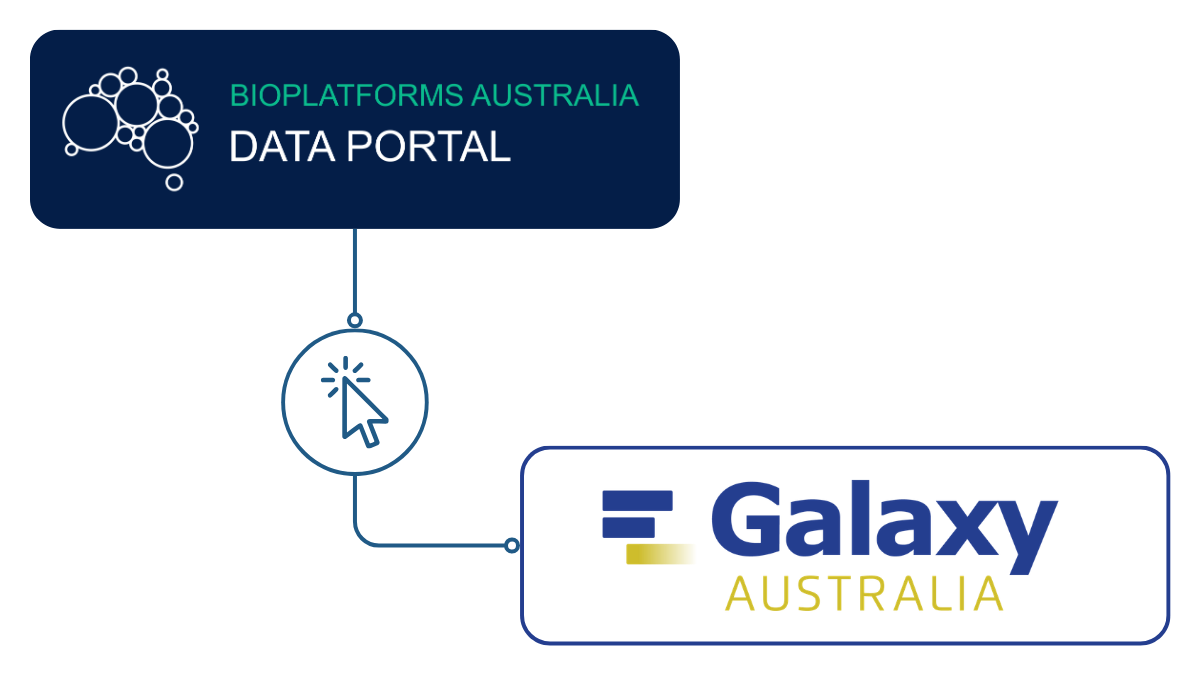
The Bioplatforms Data Portal hosts over 400TB of valuable reference molecular life sciences data covering agriculture, biomedicine, the environment and industry. The data is generated by national collaborative projects using integrated ‘omics infrastructure to generate high-impact data and knowledge resources to support some of Australia’s biggest scientific challenges. The need to move data into an analysis environment like Galaxy Australia has now become very simple.
Biologist and bioinformatician, Dr Amy Tims, performs data QC, genome assembly, and data curation for the Australian Fish Genomics Initiative established by Bioplatforms Australia and Minderoo Foundation. Consisting of genomics, genetics and transcriptomics data from 56 partner projects representing fish species from all major Australian habitats, access to this huge volume of high-quality data is valuable for research into freshwater, estuarine and marine environments. Amy stated:
‘Being able to move data straight over to Galaxy from the Data Portal without having to copy-paste lots of URLs or download files first saves a lot of time and effort. The new connection makes it super-easy to grab your data and start analysing without any fiddly intermediate steps’
This integration was made possible by the introduction of the single-sign on system, BioCommons Access. Aiming to become a universal "key" to securely find, analyse, and move biological data, 3131 existing users of the Galaxy Australia and Bioplatforms Data Portal services were smoothly migrated across to the new system, and 3993 brand new accounts have signed up since March 2026.
What are the key benefits of BioCommons Access?
Single sign-on access to multiple analysis and data services
Streamlined use of Galaxy Australia and the Bioplatforms Australia Data Portal - other services coming soon!
A central portal to manage your user profile across services
Connection to curated bundles of tools and data
Read more about how National supercomputing and expertise to enable the Australian Fish Genomics Initiative
Sign up for BioCommons Access
Unlocking multi-omics data to transform cardiovascular precision medicine
The Australian Cardiovascular disease Data Commons (ACDC) is launching as a cloud-based research platform built to accelerate the discovery of new risk markers for heart attack and stroke.
The Australian Cardiovascular disease Data Commons (ACDC) is launching as a cloud-based research platform built to accelerate the discovery of new risk markers for heart attack and stroke. The ACDC aims to build a secure, scalable, internationally integrated data infrastructure connected to best practice analysis platforms to enable the identification of novel insights, therapeutic targets and predictive biomarkers for coronary artery disease. Ultimately, the platform will facilitate a translational pipeline to ensure the deployment and evaluation of these predictors within clinical practice.
Why is a national data commons needed for cardiovascular disease
There is a current, known clinical gap, with up to 27% of heart attack patients having none of the well-known risk factors when they initially present to a GP. These can include high blood pressure, cholesterol, diabetes or smoking, and many people with coronary artery disease go on to have a second, life-threatening event despite optimal treatment. The ACDC aims to tackle this gap by securely pooling multi-omics data, longitudinal outcomes, and imaging from approximately 400,000 individuals across 18 Australian cohorts.
Prof Peter J. Meikle (Project Lead, Baker Heart and Diabetes Institute) highlights the urgency behind the project:
‘We need to understand what's really driving disease in these patients who are flying under the radar. This data commons will speed up how quickly new health technologies reach patients, and we expect it will generate a new precision medicine ecosystem in Australia.’
Led by the Baker Institute, contributions from a diverse group of participants are co-ordinated by BioCommons. The Baker Institute, the Australian Cardiovascular Alliance (ACvA), the University of Sydney, 23Strands, CSL Limited, BioCommons, data custodians and other partners are working together on infrastructure establishment, cohort onboarding and harmonisation, testing, validation, use case exploration, user experience, documentation, training, governance and intellectual property arrangements. BioCommons leads the implementation of the critical digital infrastructure underpinning the ACDC as part of the Australian BioCommons Human Genome Informatics activity.
Find out more at the online launch webinar
If you would like to learn more, you are invited to join a live webinar on 30 September 2026, 12 - 1 pm AEST. The session, featuring Prof Peter J. Meikle and Dr Tingting Wang (Baker Institute), and Prof Bernie Pope (Australian BioCommons), will explore how ACDC connects researchers to high-throughput data and global analysis environments.
Key topics include:
Development of the data commons: an overview of the cloud infrastructure, data harmonisation processes, and federated standards built on the Gen3 platform
Research value of the platform: how secure access to pooled multi-omics, genomic, and imaging cohorts enables researchers to discover new risk markers and test Polygenic Risk Scores.
Future clinical applications: how the ACDC will streamline translational pipelines to bring new diagnostic tools into clinical practice.